One Provider, Everywhere
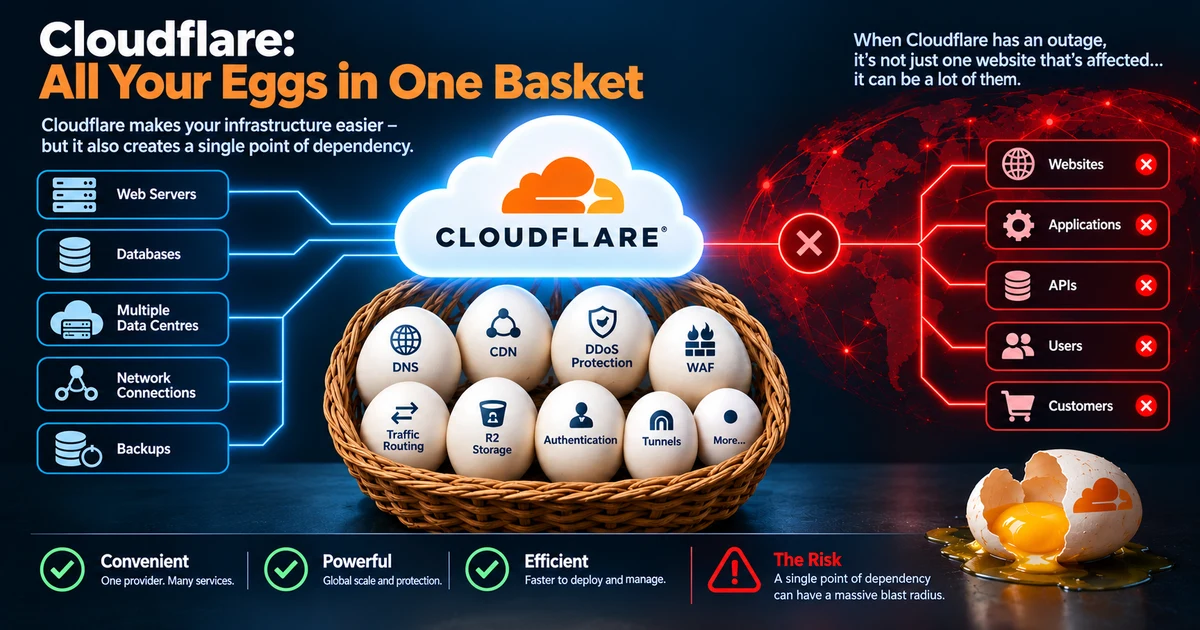
Cloudflare is everywhere. From home labs and hobby projects to banks, SaaS platforms and some of the largest websites on the internet, organisations rely on it for DNS, CDN, DDoS protection, WAF (Web Application Firewall), traffic routing, storage, authentication and Cloudflare Tunnel.
The attraction is obvious. One provider can make a huge amount of internet infrastructure easier to deploy and manage.
But there is a trade-off, and it scales with how much you consolidate:
The trade-off The more infrastructure you put behind one provider, the greater the impact when that provider has a serious outage.
Cloudflare has had a number of significant incidents over the years. Some were caused by software or configuration changes inside Cloudflare. Others involved failures in services that customers had come to depend upon. 2019 was different again — an external BGP route leak that still managed to affect traffic destined for Cloudflare, without Cloudflare making a single mistake of its own.
The common theme is dependency.
Cloudflare Outages at a Glance
| Date | Incident | What happened | Approx. duration |
|---|---|---|---|
| 20 Feb 2026 | BYOIP route withdrawal | A software bug caused approximately 1,100 customer IP prefixes to be withdrawn from BGP. | 6h 7m |
| 18 Nov 2025 | Bot Management failure | A database permissions change produced an oversized Bot Management configuration file, causing core proxy failures. | ~5h 46m |
| 21 Mar 2025 | R2 credential failure | New storage credentials were deployed to the wrong environment, causing R2 authentication failures. | 1h 7m |
| 17 Sep 2024 | IPv4 prefix withdrawal | A software error during routine maintenance withdrew 15 IPv4 prefixes, affecting 1,661 websites. | ~1h |
| 4 Oct 2023 | 1.1.1.1 DNS failure | Stale DNS root-zone data caused DNSSEC validation failures, and the resolver began returning elevated SERVFAIL responses. | 4h |
| 21 Jun 2022 | Global network outage | A routing configuration change took 19 major data centres offline, affecting around 50% of global requests. | ~1h 15m |
| 24 Jun 2019 | BGP route leak | An external routing error diverted Cloudflare traffic through a small network, causing widespread congestion. | ~3h |
These aren’t all the same type of failure. They happened at different layers — routing, DNS, storage, application infrastructure, configuration. But customers experience the same final result either way:
The result Cloudflare becomes unavailable, and the services sitting behind it become unavailable with it.
20 February 2026 — The BYOIP Route Deletion
Perhaps the clearest example of centralised infrastructure creating a large blast radius.
Cloudflare’s Bring Your Own IP customers use Cloudflare to advertise their own IP prefixes to the internet. During a software change to the addressing system, a bug caused a cleanup process to misread an API request. Instead of identifying the specific prefixes that were supposed to be removed, the system treated every returned BYOIP prefix as a candidate for deletion.
Approximately 1,100 prefixes were withdrawn from the global BGP routing table. The incident lasted 6 hours and 7 minutes. Affected customers could find their applications perfectly healthy but simply unreachable, because the routes leading to them had disappeared.
Cloudflare described the cause as an internal software change, not a cyberattack. That distinction matters. Nothing had to be wrong with the customer’s server. Nothing had to be wrong with the customer’s application. The dependency in front of it had failed.
18 November 2025 — The Bot Management Crash
One of Cloudflare’s most significant outages in recent years. The network began returning large numbers of HTTP 5xx errors.
The root cause was a change to database permissions that caused a query to produce duplicate data. That data fed into a Bot Management configuration file, which grew beyond a hard-coded limit in Cloudflare’s proxy software. The software failed trying to process the oversized file.
The incident reached core CDN and security services, plus dependents including Workers KV and Cloudflare Access. Cloudflare states that most core traffic was restored by 14:30 UTC, with all systems functioning normally by 17:06 UTC.
Again, the interesting part isn’t that a software bug existed. It’s the blast radius. A database permissions change ultimately touched traffic passing through a huge portion of Cloudflare’s network.
21 March 2025 — R2 Credential Failure
Cloudflare’s R2 object storage service went down globally for 1 hour and 7 minutes. During that window:
- 100% of R2 writes failed
- Approximately 35% of reads failed globally
- Cloudflare Images uploads failed
- Stream uploads failed
- Log delivery was delayed
- Other services dependent on R2 were also affected
The root cause was a credential rotation error. New credentials were deployed to a development environment instead of the production R2 Gateway. When the old credentials were then removed, production could no longer authenticate with the storage infrastructure.
A useful example of dependency chains in practice. A customer might not use R2 directly at all, and still be affected, because another Cloudflare service they do use depends on R2. One dependency becomes another, which becomes another.
17 September 2024 — IPv4 Prefix Withdrawal
During routine maintenance, Cloudflare inadvertently stopped announcing 15 IPv4 prefixes. Those prefixes contained 1,661 customer websites. IPv4 traffic to those sites couldn’t reach Cloudflare, producing connectivity failures for roughly an hour.
Cloudflare attributed it to an internal software error rather than an attack. IPv6 traffic was unaffected. Once again, the origin websites themselves could have been running perfectly normally. The problem was further upstream. The routes to them had disappeared.
4 October 2023 — The 1.1.1.1 DNS Failure
DNS is one of the foundations of the internet. Cloudflare operates the 1.1.1.1 public resolver, and in October 2023 its resolver systems failed to properly process a change to the DNS root zone. The stale root-zone data eventually contained expired DNSSEC signatures.
As those signatures expired, resolver systems began returning SERVFAIL responses. The incident began at 07:00 UTC and normal responses returned by roughly 11:00 UTC — four hours.
This illustrates another point worth holding onto: your web server doesn’t have to be offline for your website to be effectively offline. If users can’t resolve the address in the first place, they never get as far as your server to find out it was fine.
21 June 2022 — Global Data Plane Breakdown
A routing configuration change took 19 Cloudflare data centres offline. Those locations represented only around 4% of Cloudflare’s total network, but Cloudflare reported the outage affected approximately 50% of global requests, because those particular locations handled a disproportionate share of its traffic. Amsterdam, Atlanta, Ashburn, Frankfurt, London, Los Angeles, Singapore and Tokyo were among them.
The cause was a change to BGP prefix-advertisement policy that withdrew critical prefixes. The outage began at 06:27 UTC and was resolved by 07:42 UTC.
Perhaps the clearest demonstration of the concentration problem available. Cloudflare had hundreds of data centres. It still didn’t matter. A configuration error touching a relatively small proportion of its locations was enough to affect roughly half the requests passing through the entire network.
24 June 2019 — The Verizon BGP Route Leak
Worth including because it demonstrates Cloudflare doesn’t have to make a mistake for Cloudflare-dependent services to be affected.
A small network in Pennsylvania advertised more-specific BGP routes. Those routes were passed to Verizon, which propagated them more widely than it should have. Traffic destined for Cloudflare was consequently pulled toward a small network with nowhere near the capacity to handle it.
Cloudflare reported losing approximately 15% of its global traffic at the worst point. Amazon and other major internet properties were affected too.
This wasn’t a Cloudflare software failure. It still affected Cloudflare customers. When your infrastructure depends on a large intermediary, failures in the systems surrounding that intermediary become your problem too, whether or not the intermediary did anything wrong.
The Common Thread
These incidents weren’t identical. Software bugs, configuration errors, credential management, DNS, BGP routing, an external network entirely outside Cloudflare’s control. But they all point at the same architectural concern:
The concern Cloudflare can become a single point of dependency for a very large number of otherwise independent services.
Your infrastructure might look resilient on paper — multiple servers, replicated databases, multiple availability zones, redundant power. But if everything ultimately has to pass through one provider on the way out, that provider is still part of your failure domain, no matter how much redundancy sits behind it.
All Your Eggs in One Basket
This is the real concern with excessive dependence on any single infrastructure provider. Cloudflare makes it extremely easy to consolidate — DNS, CDN, DDoS protection, WAF, bot management, authentication, traffic routing, object storage, application deployment, tunnels, logging. Every individual service might make perfect sense on its own.
The danger arrives when they’re all used together. If Cloudflare has a serious incident, you may discover that your apparently redundant infrastructure isn’t redundant at all. You’ve simply moved the single point of failure further up the stack, and out of your own hands.
The Hidden Single Point of Failure
Picture an organisation with multiple web servers, replicated databases, multiple data centres, redundant network connections, automated failover and regular backups. It looks resilient.
Now put Cloudflare in front of all of it. A failure affecting its routing, DNS, authentication or CDN — whichever piece your architecture happens to depend on — and your servers can remain perfectly healthy, your databases perfectly healthy, your network perfectly healthy, while your users still can’t reach you.
That is the danger of centralised dependency. It doesn’t care how well-engineered everything underneath it is.
Does This Mean You Shouldn’t Use Cloudflare?
These outages don’t demonstrate that Cloudflare is uniquely incapable of running reliable infrastructure. Large infrastructure providers fail. All of them, eventually. The more useful lesson is that Cloudflare should be treated as infrastructure, not merely as a feature bolted onto your infrastructure. If your business depends on it, its failure needs to be in your disaster-recovery plan, not a footnote you discover during the outage.
Ask yourself the questions that actually matter:
- Can users reach the service without Cloudflare?
- Can DNS be moved elsewhere quickly?
- Do you have an alternative CDN or reverse proxy?
- Can administrators access your infrastructure independently?
- Does your application depend on Cloudflare APIs?
- Is critical data stored exclusively within Cloudflare?
- Could you operate using another provider?
- Have you actually tested the process, rather than just assumed it would work?
If the answer to several of those is no, Cloudflare isn’t protecting your infrastructure. It is your infrastructure.
Resilience Means Having Somewhere Else to Go
You don’t necessarily need to abandon Cloudflare. You may simply need to avoid making it indispensable — a second DNS provider, an alternative CDN configuration, independent management access, copies of critical data kept outside the provider, a tested route around the service for when circumstances require it. The exact solution depends on the organisation. The principle doesn’t.
The principle If one provider failing can take your entire service offline, you don’t have complete redundancy. You have redundancy underneath a single dependency. And that dependency is a basket.
The question is simply how many eggs you’ve put in it.